

Automatic Speech Recognition
Transformers
ONNX
PEFT
whisper
polywhisper
indic-asr
hindi-asr
tamil-speech-recognition
telugu-stt
bengali-asr
marathi-speech-to-text
speech-recognition
multilingual
lora
hindi
tamil
telugu
bengali
marathi
indic-languages
indian-languages
speech-to-text
low-resource-asr
fleurs
indicvoices
quantized
efficient-asr
edge-asr
Eval Results (legacy)

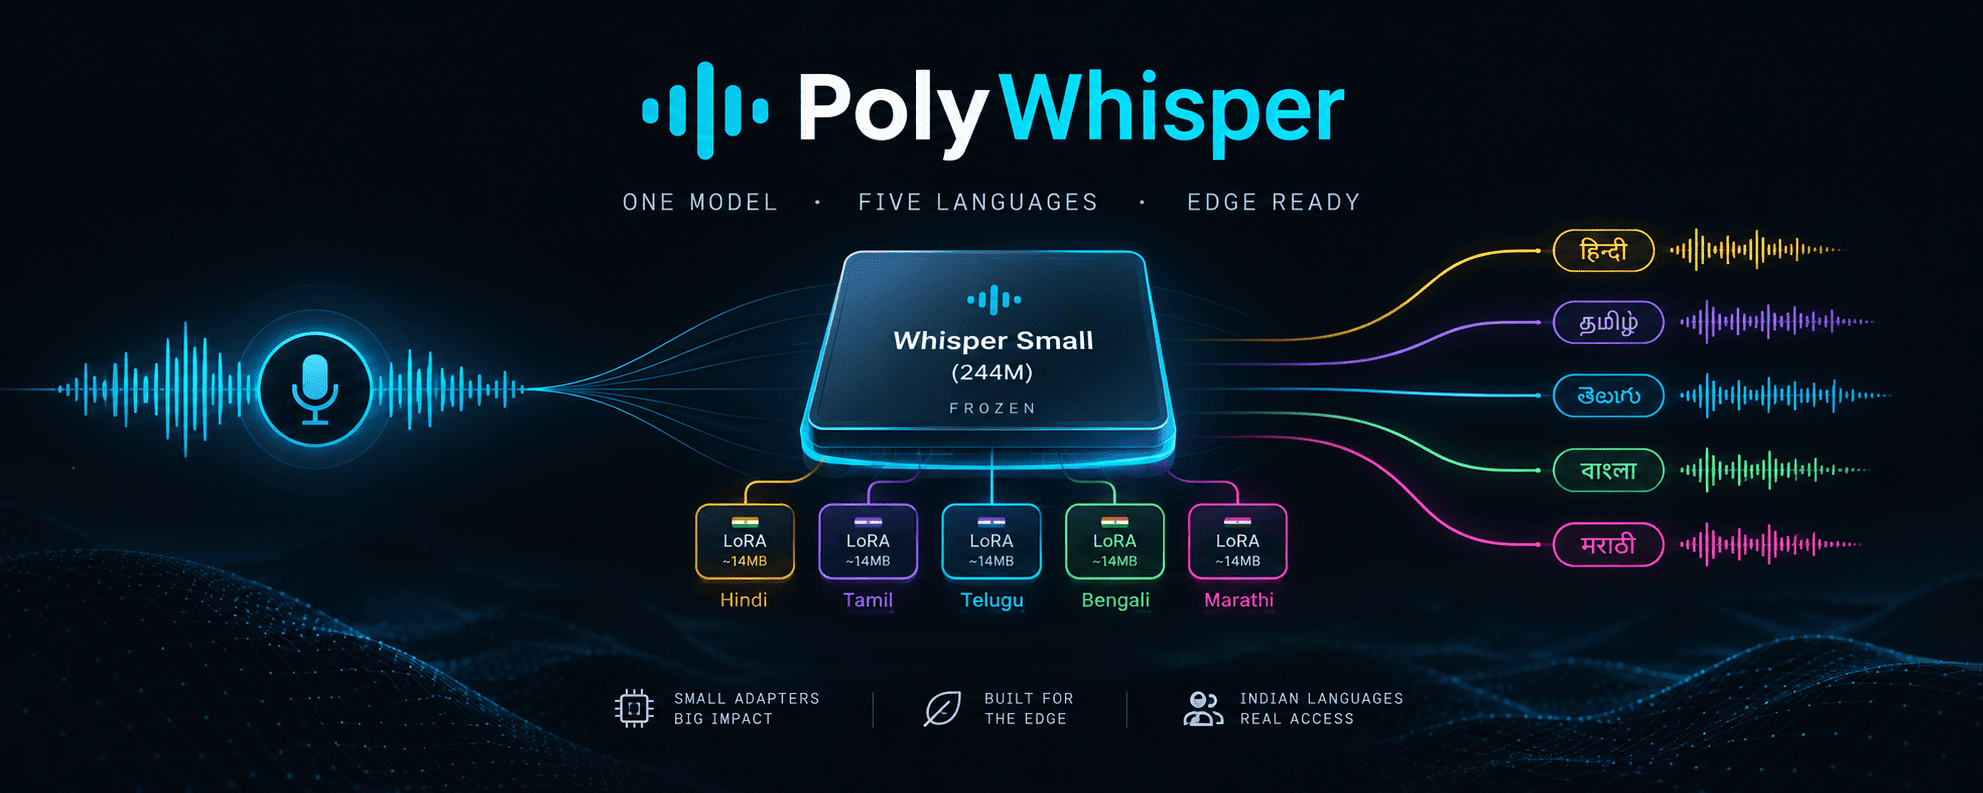
docs: add polywhisper banner
Browse files
README.md
CHANGED
|
@@ -96,6 +96,8 @@ model-index:
|
|
| 96 |
name: WER (beam=1, normalized)
|
| 97 |
---
|
| 98 |
|
|
|
|
|
|
|
| 99 |
[](https://huggingface.co/eulogik/polywhisper)
|
| 100 |
[](https://github.com/eulogik/PolyWhisper)
|
| 101 |
[](https://github.com/eulogik/PolyWhisper/releases)
|
|
|
|
| 96 |
name: WER (beam=1, normalized)
|
| 97 |
---
|
| 98 |
|
| 99 |
+
|
| 100 |
+
|
| 101 |
[](https://huggingface.co/eulogik/polywhisper)
|
| 102 |
[](https://github.com/eulogik/PolyWhisper)
|
| 103 |
[](https://github.com/eulogik/PolyWhisper/releases)
|