

Automatic Speech Recognition
Transformers
ONNX
PEFT
whisper
polywhisper
indic-asr
hindi-asr
tamil-speech-recognition
telugu-stt
bengali-asr
marathi-speech-to-text
speech-recognition
multilingual
lora
hindi
tamil
telugu
bengali
marathi
indic-languages
indian-languages
speech-to-text
low-resource-asr
fleurs
indicvoices
quantized
efficient-asr
edge-asr
Eval Results (legacy)
File size: 13,747 Bytes
2e9e5ea 80d9c31 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d c3d8359 cba584d 2e9e5ea b6d5796 cba584d 80d9c31 2e9e5ea 35703ce cba584d 80d9c31 cba584d c3d8359 9585155 35703ce cba584d 2e9e5ea cba584d 0bf87c1 c3d8359 0bf87c1 cba584d 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 0bf87c1 c3d8359 35703ce 9585155 cba584d 35703ce 9585155 2e9e5ea cba584d 9585155 05b64d2 19afd17 c3d8359 19afd17 cba584d 449f3f9 cba584d 9585155 c3d8359 cba584d 9585155 cba584d 449f3f9 05b64d2 449f3f9 cba584d 449f3f9 05b64d2 2e9e5ea cba584d 05b64d2 cba584d 05b64d2 449f3f9 05b64d2 cba584d 449f3f9 05b64d2 cba584d 05b64d2 8194491 05b64d2 449f3f9 cba584d 2e9e5ea 449f3f9 8194491 9585155 8194491 449f3f9 cba584d 05b64d2 cba584d 05b64d2 cba584d 05b64d2 cba584d 2e9e5ea cba584d 2e9e5ea 9585155 2e9e5ea cba584d 2e9e5ea cba584d 2e9e5ea cba584d 449f3f9 cba584d 05b64d2 cba584d 19afd17 449f3f9 cba584d 2e9e5ea 80d9c31 2e9e5ea 9585155 cba584d 2e9e5ea 449f3f9 05b64d2 cba584d 05b64d2 80d9c31 cba584d | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 203 204 205 206 207 208 209 210 211 212 213 214 215 216 217 218 219 220 221 222 223 224 225 226 227 228 229 230 231 232 233 234 235 236 237 238 239 240 241 242 243 244 245 246 247 248 249 250 251 252 253 254 255 256 257 258 259 260 261 262 263 264 265 266 267 268 269 270 271 272 273 274 275 276 277 278 279 280 281 282 283 284 285 286 287 288 289 290 291 292 293 294 295 296 297 298 | ---
language:
- hi
- ta
- te
- bn
- mr
license: mit
library_name: transformers
pipeline_tag: automatic-speech-recognition
base_model: openai/whisper-small
tags:
- polywhisper
- indic-asr
- hindi-asr
- tamil-speech-recognition
- telugu-stt
- bengali-asr
- marathi-speech-to-text
- speech-recognition
- multilingual
- lora
- whisper
- hindi
- tamil
- telugu
- bengali
- marathi
- indic-languages
- indian-languages
- automatic-speech-recognition
- speech-to-text
- low-resource-asr
- fleurs
- indicvoices
- onnx
- quantized
- efficient-asr
- edge-asr
- peft
datasets:
- ai4bharat/indicvoices-st
- google/fleurs
model-index:
- name: PolyWhisper v9 (Whisper-Small + Per-Language LoRA)
results:
- task:
type: automatic-speech-recognition
name: Hindi Speech Recognition
dataset:
name: FLEURS Hindi (hi_in)
type: google/fleurs
metrics:
- type: wer
value: 46.3
name: WER (beam=1, normalized)
- task:
type: automatic-speech-recognition
name: Tamil Speech Recognition
dataset:
name: FLEURS Tamil (ta_in)
type: google/fleurs
metrics:
- type: wer
value: 70.1
name: WER (beam=1, normalized)
- task:
type: automatic-speech-recognition
name: Telugu Speech Recognition
dataset:
name: FLEURS Telugu (te_in)
type: google/fleurs
metrics:
- type: wer
value: 100.1
name: WER (beam=1, normalized)
- task:
type: automatic-speech-recognition
name: Bengali Speech Recognition
dataset:
name: FLEURS Bengali (bn_in)
type: google/fleurs
metrics:
- type: wer
value: 130.2
name: WER (beam=1, normalized)
- task:
type: automatic-speech-recognition
name: Marathi Speech Recognition
dataset:
name: FLEURS Marathi (mr_in)
type: google/fleurs
metrics:
- type: wer
value: 116.9
name: WER (beam=1, normalized)
---
[](https://huggingface.co/eulogik/polywhisper)
[](https://github.com/eulogik/PolyWhisper)
[](https://github.com/eulogik/PolyWhisper/releases)
[](https://opensource.org/licenses/MIT)
[](https://www.python.org/downloads/)
[](https://pytorch.org/)
[](https://onnxruntime.ai/)
    
# 🎙️ PolyWhisper v9 — Efficient Multilingual Indic ASR
> by [Eulogik](https://eulogik.com) — Frontier Edge AI · Vernacular Intelligence · [eulogik.com](https://eulogik.com)
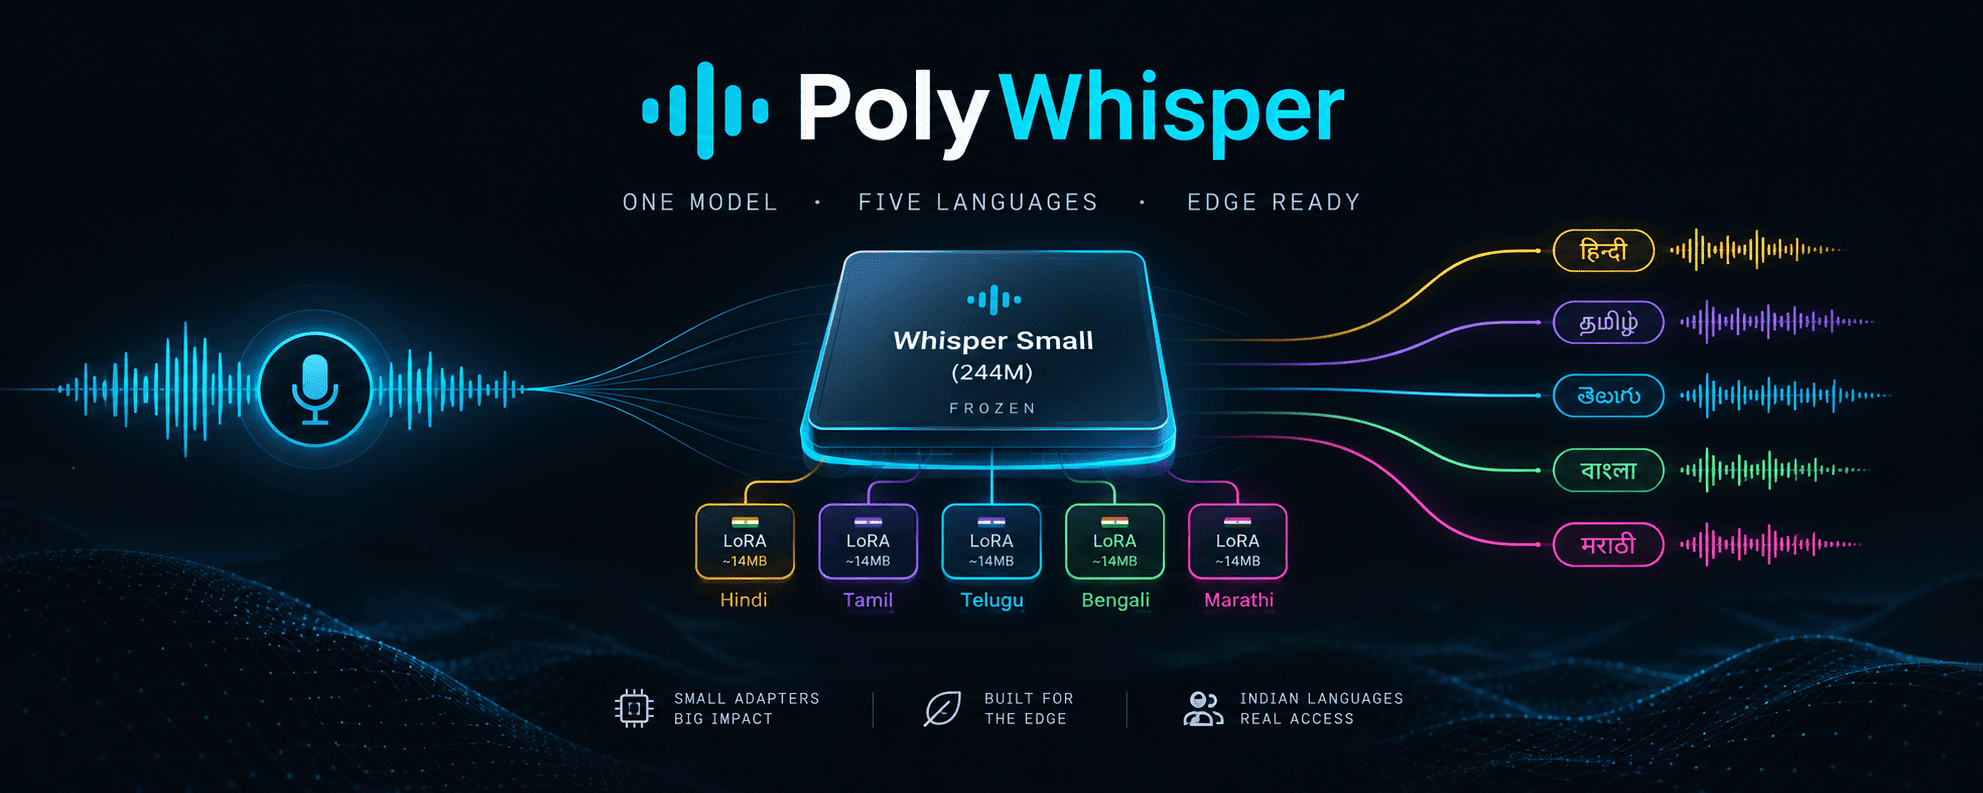
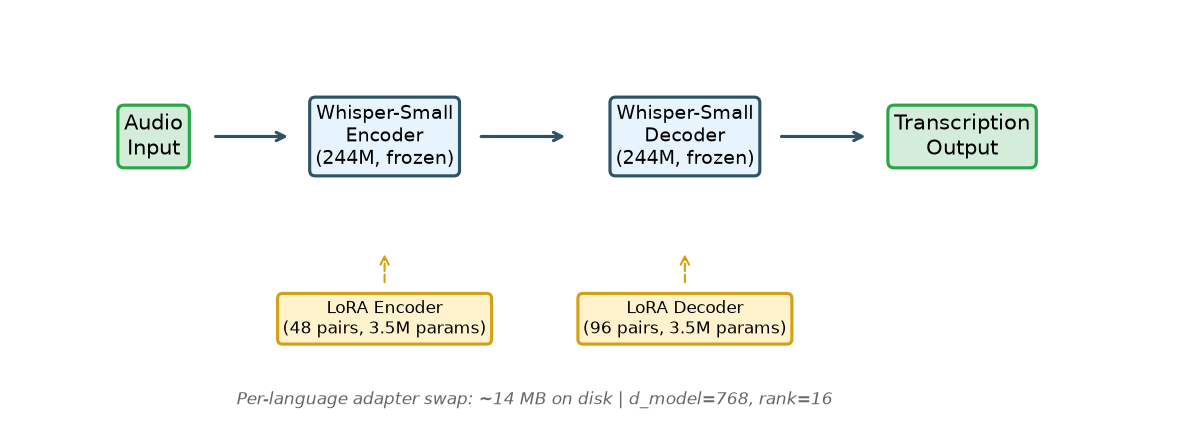
> **TL;DR:** PolyWhisper v9 is a research-ready automatic speech recognition (ASR) system for **Hindi, Tamil, Telugu, Bengali, and Marathi**. It pairs a **frozen OpenAI Whisper-Small backbone (244M params)** with tiny **per-language LoRA adapters (~14MB each)**. Bengali WER drops **−28.2%** and Marathi **−75.4%** versus the no-augmentation baseline — at roughly **1% of the storage cost** of full fine-tuning.
## ✨ Why PolyWhisper?
| | Full fine-tune (per language) | **PolyWhisper v9** |
|---|---|---|
| Storage per language | ~1.5 GB | **~14 MB (100× smaller)** |
| Backbone | retrained each time | **frozen once, shared by all 5** |
| Bengali (bn) FLEURS WER | 181.3 (baseline) | **130.2 (−28.2%)** |
| Marathi (mr) FLEURS WER | 474.9 (baseline) | **116.9 (−75.4%)** |
| Telugu (te) FLEURS WER | 103.0 (baseline) | **100.1 (−2.8%)** |
| Hindi (hi) FLEURS WER | 43.0 (baseline) | **46.3** |
| Tamil (ta) FLEURS WER | 68.2 (baseline) | **70.1** |
| CPU deployment | heavy | **ONNX INT8, no GPU needed** |
*WER = word error rate (lower is better). FLEURS test set, beam=1, punctuation-normalized scoring.*
## 📊 Benchmarks (FLEURS, beam=1, normalized WER)
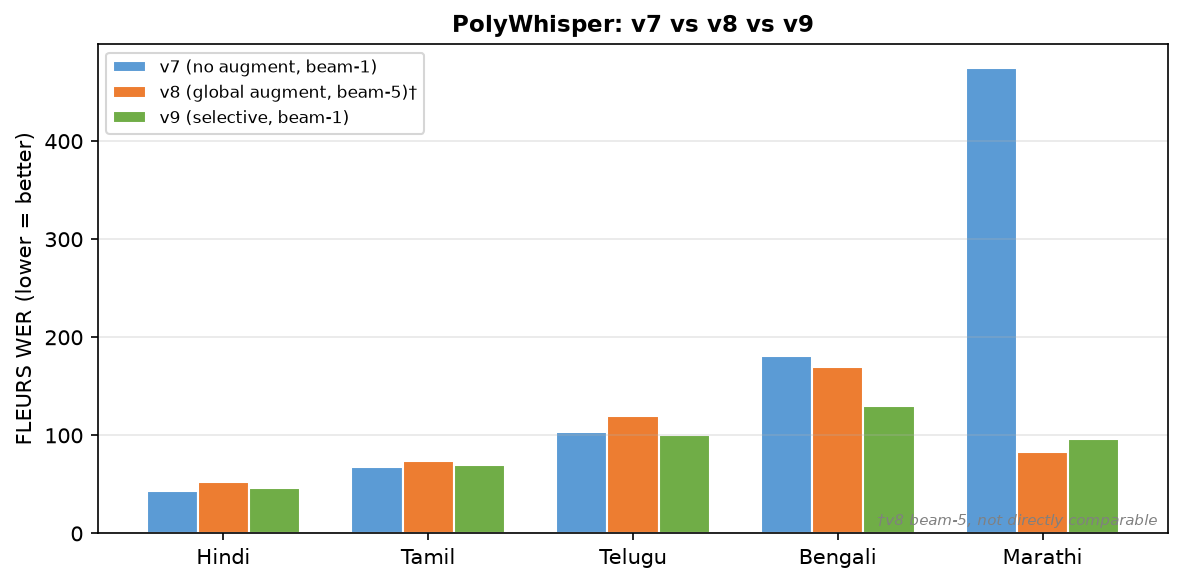
| Language | Code | Script | v7 (no augment) | **v9 final** | Δ vs v7 |
|---|---|---|---|---|---|
| Hindi | `hi` | Devanagari | 43.0 | **46.3** | +7.7% |
| Tamil | `ta` | Tamil | 68.2 | **70.1** | +2.8% |
| Telugu | `te` | Telugu | 103.0 | **100.1** | ✅ **−2.8%** |
| Bengali | `bn` | Bengali | 181.3 | **130.2** | ✅ **−28.2%** |
| Marathi | `mr` | Devanagari | 474.9 | **116.9** | ✅ **−75.4%** |
### 🧪 The v9 finding: augment per language, not globally
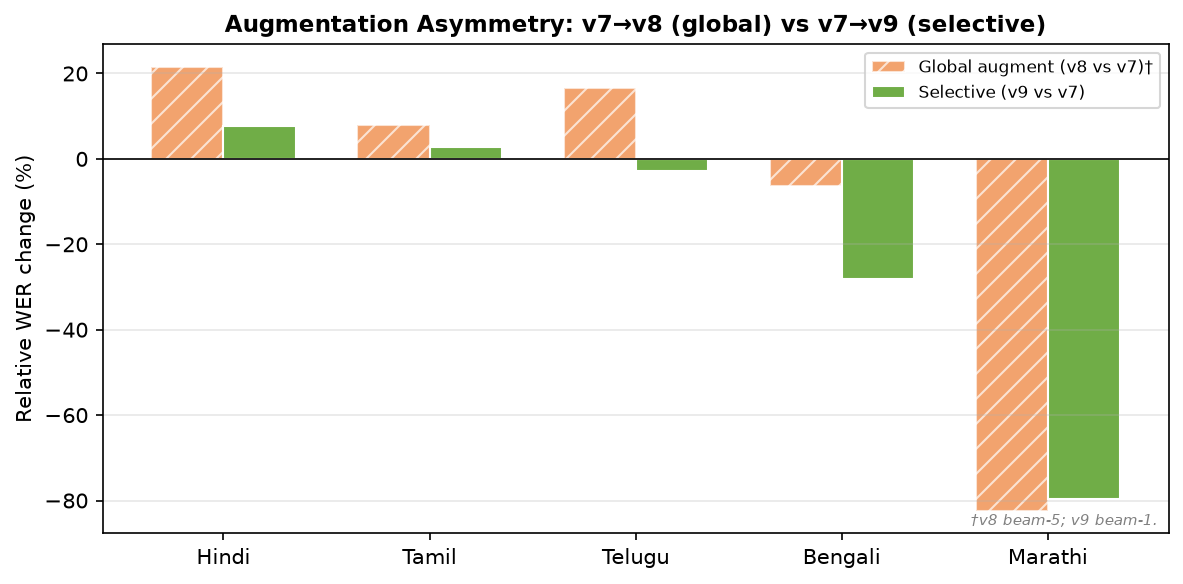
Training with SpecAugment + speed perturbation on **all** languages damaged Hindi/Tamil (token-loop degeneration) while massively helping Bengali/Marathi. The v9 recipe augments **only `bn`/`mr`** and trains `hi`/`ta`/`te` clean:
| Language | Augmentation | Result |
|---|---|---|
| Hindi, Tamil, Telugu | none (clean) | avoids global-augment damage; stays near the no-augment baseline |
| Bengali, Marathi | SpecAugment + 0.9×/1.1× speed perturb | large gains on hard languages |
### 🎯 Decoding: per-language beam widths (measured, full FLEURS test)
Beam-5 + repetition penalty 1.3 helps every language **except Telugu**, where beam search collapses into repeated-token loops (0/472 perfect samples, 326/472 over 100% WER). The library/CLI defaults encode this (`num_beams=None` → per-language optimal):
| Language | beam-1 | beam-5 + rep 1.3 | Shipped default |
|---|---|---|---|
| Hindi | 46.3 | **45.0** (−2.8%) | beam-5 |
| Tamil | 70.1 | **68.6** (−2.2%) | beam-5 |
| Telugu | **100.1** | 120.5 (+20.4% ⚠️) | **beam-1** |
| Bengali | 130.2 | **126.4** (−2.9%) | beam-5 |
| Marathi | 116.9 | **91.5** (−21.7%) | beam-5 |
## 📦 Which adapter should I use?
| Language | Adapter file | Backbone | WER |
|---|---|---|---|
| Hindi (`hi`) | [`polywhisper_output_hi/adapters_v3/hi_best_clean.pt`](https://huggingface.co/eulogik/polywhisper/resolve/main/polywhisper_output_hi/adapters_v3/hi_best_clean.pt) | `openai/whisper-small` | 46.3 |
| Tamil (`ta`) | [`polywhisper_output_ta/adapters_v3/ta_best_clean.pt`](https://huggingface.co/eulogik/polywhisper/resolve/main/polywhisper_output_ta/adapters_v3/ta_best_clean.pt) | `openai/whisper-small` | 70.1 |
| Telugu (`te`) | [`polywhisper_output_gpu0/adapters_v3/te_best_prod.pt`](https://huggingface.co/eulogik/polywhisper/resolve/main/polywhisper_output_gpu0/adapters_v3/te_best_prod.pt) | `openai/whisper-small` | 100.1 |
| Bengali (`bn`) | [`polywhisper_output_gpu0/adapters_v3/bn_best_prod.pt`](https://huggingface.co/eulogik/polywhisper/resolve/main/polywhisper_output_gpu0/adapters_v3/bn_best_prod.pt) | `openai/whisper-small` | 130.2 |
| Marathi (`mr`) | [`polywhisper_output_gpu1/adapters_v3/mr_best_prod.pt`](https://huggingface.co/eulogik/polywhisper/resolve/main/polywhisper_output_gpu1/adapters_v3/mr_best_prod.pt) | `openai/whisper-small` | 116.9 |
All adapters are rank-16 LoRA (decoder + encoder attention), ~14MB each. Backbone weights are **not** included — they load from `openai/whisper-small` at runtime. The `_prod` suffix is the v9 production-run tag, not an augmentation marker: Telugu was trained clean in the selective v9 recipe.
## 🚀 Quickstart
```bash
pip install -e .
```
```bash
# Hindi speech to text
polywhisper transcribe audio.wav --lang hi
# Tamil with JSON output
polywhisper transcribe audio.wav --lang ta --format json
# Auto-detect language, SRT subtitles
polywhisper transcribe audio.wav --format srt > subs.srt
# Batch a folder
polywhisper batch ./audio_folder/ --lang bn --output results.json
```
```python
from polywhisper import transcribe
result = transcribe("audio.wav", lang="mr")
print(result.text)
print(result.segments) # timestamped segments
```
## 🖥️ CPU-only inference (ONNX Runtime)
Export INT8-quantized ONNX graphs (no PyTorch, no GPU needed at inference):
```bash
polywhisper export --lang hi --variant prod --int8
```
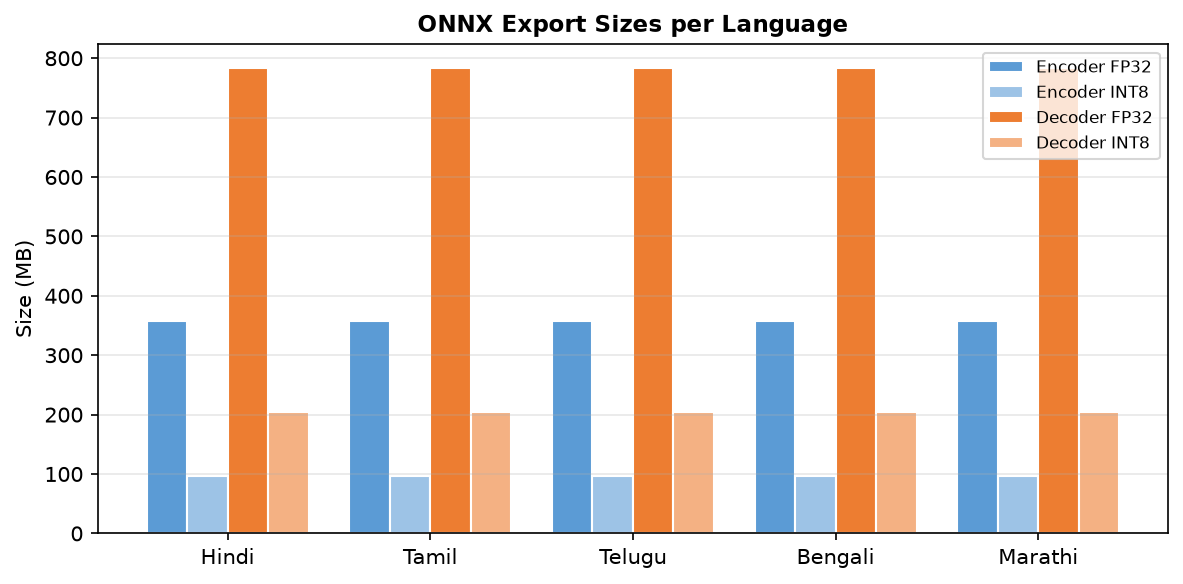
Pre-exported v9 graphs live under `export/onnx/` on the [Hub](https://huggingface.co/eulogik/polywhisper/tree/main/export/onnx) — per language, fp32 + INT8:
| Lang | Encoder (fp32 / INT8) | Decoder (fp32 / INT8) |
|---|---|---|
| hi | 358MB / 97MB | 784MB / 204MB |
| ta | 358MB / 97MB | 784MB / 204MB |
| te | 358MB / 97MB | 784MB / 204MB |
| bn | 358MB / 97MB | 784MB / 204MB |
| mr | 358MB / 97MB | 784MB / 204MB |
Files are named `{lang}_{lang}_best_prod_{encoder,decoder}{,_int8}.onnx`. INT8 is ~4× smaller.
**Verification:** fp32 ONNX vs PyTorch max diff < 1e-3 on all five languages (encoder + decoder). End-to-end greedy spot-checks (FLEURS audio, beam=1):
| Lang | torch WER | ONNX INT8 WER |
|---|---|---|
| hi (10 samples) | 43.4% | 48.3% |
| ta (5 samples) | 100.0% | 100.0% |
| te (5 samples) | 100.0% | 101.6% |
| bn (5 samples) | 104.9% | 118.7% |
| mr (5 samples) | 82.9% | 89.4% |
*Spot-checks are tiny (5–10 utterances) so single-sentence flips move the numbers; fp32 ONNX is at parity with torch. INT8 trades a few points for 4× smaller files.*
## 🏋️ Training recipe (reproducible)
- **Data:** [IndicVoices-ST](https://huggingface.co/datasets/ai4bharat/indicvoices-st) (~19–20k clips/language) · **Eval:** [FLEURS](https://huggingface.co/datasets/google/fleurs)
- **Backbone:** `openai/whisper-small`, frozen · **Adapters:** LoRA rank-16, encoder + decoder attention
- **Schedule:** 3–5 epochs/language, batch 4, AdamW, cosine LR (peak 1e-4), 2× NVIDIA T4
- **Augmentation (v9):** SpecAugment + speed perturb for `bn`/`mr` only; `hi`/`ta`/`te` clean
- **Selection:** WER-gated checkpoints (`*_best_*.pt`) on FLEURS dev slices
- **Code:** [`train_v3.py`](https://github.com/eulogik/PolyWhisper/blob/main/train_v3.py) · orchestrator [`kaggle_train_resumable.py`](https://github.com/eulogik/PolyWhisper/blob/main/kaggle_train_resumable.py) · scoring [`normalize_ortho.py`](https://github.com/eulogik/PolyWhisper/blob/main/normalize_ortho.py)
## ❓ FAQ
**What is PolyWhisper?**
PolyWhisper is an open-source Indic ASR toolkit: one frozen Whisper-Small backbone plus five small per-language LoRA adapters covering Hindi, Tamil, Telugu, Bengali, and Marathi.
**How is it different from fine-tuning Whisper?**
Full fine-tuning rewrites ~244M–1.5B weights per language. PolyWhisper freezes the backbone and trains ~3.5M LoRA parameters per language (~14MB), so five languages ship for the storage cost of a rounding error.
**Which languages are usable?**
All five ship working adapters. Hindi (46.3 WER) and Tamil (70.1) are strongest; Telugu, Bengali, and Marathi remain high-WER research adapters, useful for assistive/search/subtitle-draft workflows rather than verbatim transcription.
**Can I run it on CPU?**
Yes — export to ONNX INT8 and run with ONNX Runtime, no GPU required.
**Can I run it on a Mac?**
Yes — PyTorch MPS is supported (`Device: mps`), plus CPU via ONNX.
**What data was it trained/evaluated on?**
Trained on IndicVoices-ST conversational speech, evaluated on FLEURS read speech with punctuation-normalized, script-aware scoring.
## ⚠️ Limitations
- Absolute WER on Telugu/Bengali/Marathi is still high — usable for assistive/search/subtitle-draft workflows, not verbatim legal/medical transcription.
- Evaluated on read speech (FLEURS); spontaneous conversational accuracy will differ.
- Beam=1 numbers in the benchmark table above (paper parity); shipped defaults use beam-5 + repetition penalty 1.3 except Telugu (beam-1), see decoding table.
## 📄 License & citation
MIT. Whisper weights © OpenAI. Training data: IndicVoices-ST (CC-BY) · Eval: FLEURS (CC-BY).
```bibtex
@misc{polywhisper2026,
title = {PolyWhisper: Efficient Multilingual Indic ASR via Frozen Backbone and Per-Language LoRA Adapters},
author = {Kishore, Gautam},
year = {2026},
publisher = {HuggingFace},
url = {https://huggingface.co/eulogik/polywhisper}
}
```
## 🔗 Links
- 🌍 Eulogik: [eulogik.com](https://eulogik.com)
- 🤗 Model: [huggingface.co/eulogik/polywhisper](https://huggingface.co/eulogik/polywhisper)
- 💻 Code: [github.com/eulogik/PolyWhisper](https://github.com/eulogik/PolyWhisper)
- 🗣️ Train data: [ai4bharat/indicvoices-st](https://huggingface.co/datasets/ai4bharat/indicvoices-st)
- 🧪 Eval data: [google/fleurs](https://huggingface.co/datasets/google/fleurs)
|