


language:
  - hi
  - ta
  - te
  - bn
  - mr
license: mit
library_name: transformers
pipeline_tag: automatic-speech-recognition
base_model: openai/whisper-small
tags:
  - polywhisper
  - indic-asr
  - hindi-asr
  - tamil-speech-recognition
  - telugu-stt
  - bengali-asr
  - marathi-speech-to-text
  - speech-recognition
  - multilingual
  - lora
  - whisper
  - hindi
  - tamil
  - telugu
  - bengali
  - marathi
  - indic-languages
  - indian-languages
  - automatic-speech-recognition
  - speech-to-text
  - low-resource-asr
  - fleurs
  - indicvoices
  - onnx
  - quantized
  - efficient-asr
  - edge-asr
  - peft
datasets:
  - ai4bharat/indicvoices-st
  - google/fleurs
model-index:
  - name: PolyWhisper v9 (Whisper-Small + Per-Language LoRA)
    results:
      - task:
          type: automatic-speech-recognition
          name: Hindi Speech Recognition
        dataset:
          name: FLEURS Hindi (hi_in)
          type: google/fleurs
        metrics:
          - type: wer
            value: 46.3
            name: WER (beam=1, normalized)
      - task:
          type: automatic-speech-recognition
          name: Tamil Speech Recognition
        dataset:
          name: FLEURS Tamil (ta_in)
          type: google/fleurs
        metrics:
          - type: wer
            value: 70.1
            name: WER (beam=1, normalized)
      - task:
          type: automatic-speech-recognition
          name: Telugu Speech Recognition
        dataset:
          name: FLEURS Telugu (te_in)
          type: google/fleurs
        metrics:
          - type: wer
            value: 100.1
            name: WER (beam=1, normalized)
      - task:
          type: automatic-speech-recognition
          name: Bengali Speech Recognition
        dataset:
          name: FLEURS Bengali (bn_in)
          type: google/fleurs
        metrics:
          - type: wer
            value: 130.2
            name: WER (beam=1, normalized)
      - task:
          type: automatic-speech-recognition
          name: Marathi Speech Recognition
        dataset:
          name: FLEURS Marathi (mr_in)
          type: google/fleurs
        metrics:
          - type: wer
            value: 116.9
            name: WER (beam=1, normalized)





🎙️ PolyWhisper v9 — Efficient Multilingual Indic ASR
by Eulogik — Frontier Edge AI · Vernacular Intelligence · eulogik.com
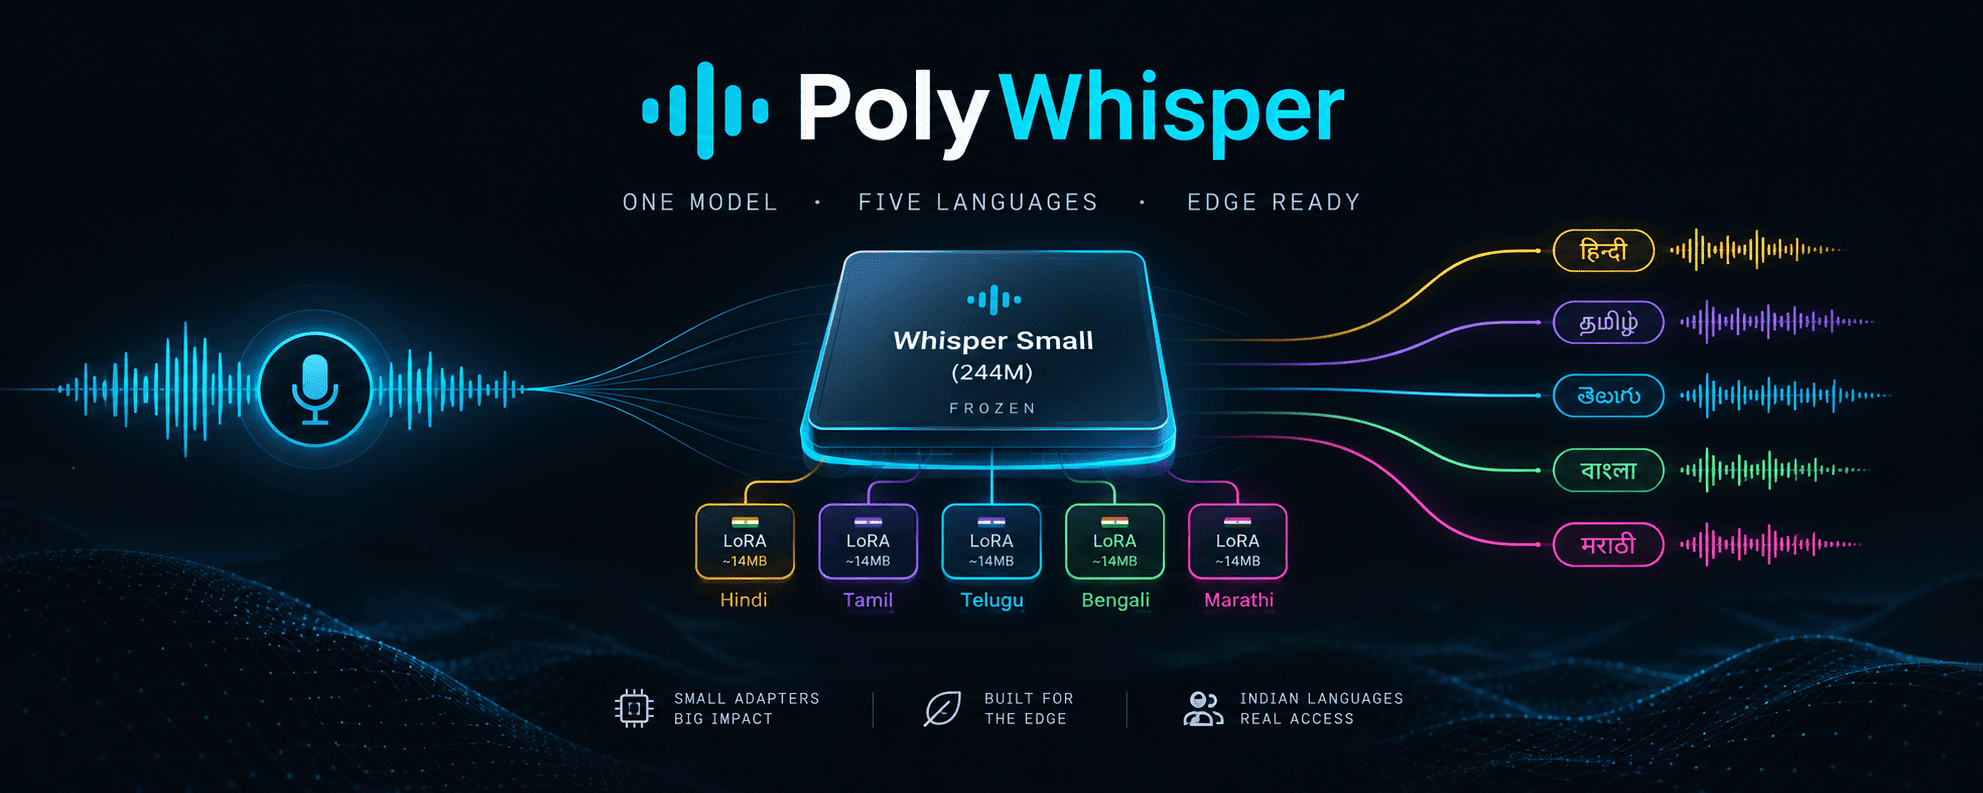
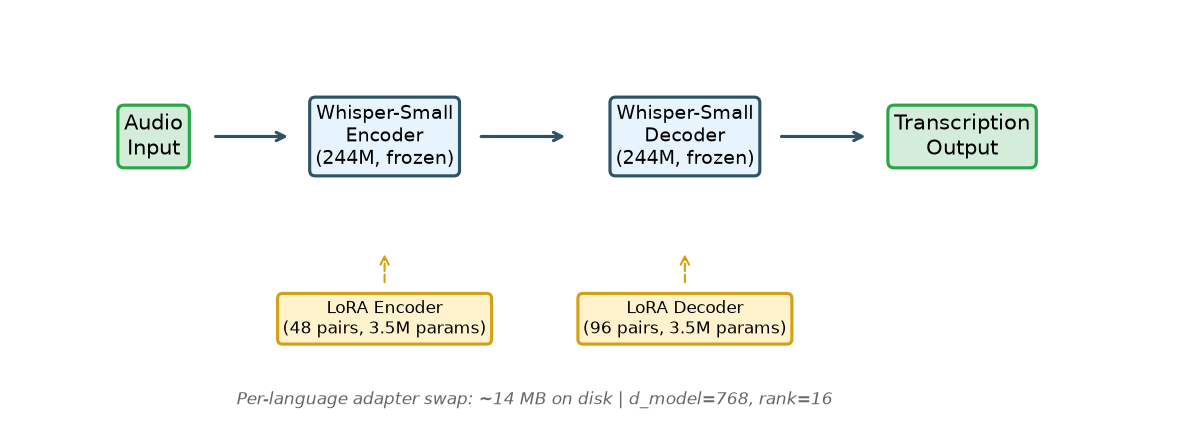
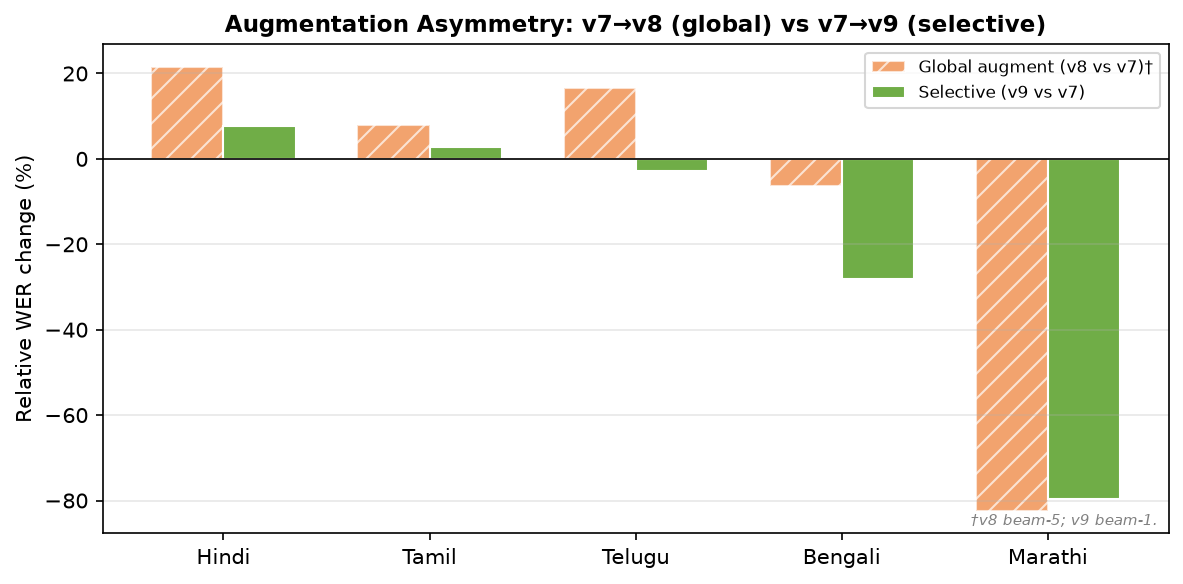
TL;DR: PolyWhisper v9 is a research-ready automatic speech recognition (ASR) system for Hindi, Tamil, Telugu, Bengali, and Marathi. It pairs a frozen OpenAI Whisper-Small backbone (244M params) with tiny per-language LoRA adapters (~14MB each). Bengali WER drops −28.2% and Marathi −75.4% versus the no-augmentation baseline — at roughly 1% of the storage cost of full fine-tuning.
✨ Why PolyWhisper?
| Full fine-tune (per language) | PolyWhisper v9 | |
|---|---|---|
| Storage per language | ~1.5 GB | ~14 MB (100× smaller) |
| Backbone | retrained each time | frozen once, shared by all 5 |
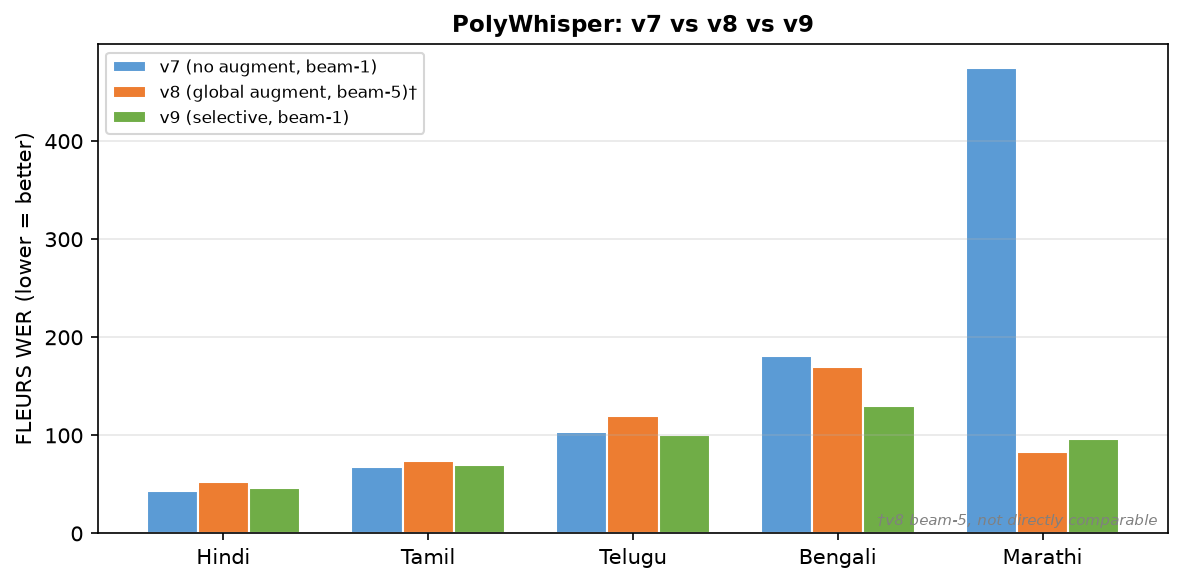
| Bengali (bn) FLEURS WER | 181.3 (baseline) | 130.2 (−28.2%) |
| Marathi (mr) FLEURS WER | 474.9 (baseline) | 116.9 (−75.4%) |
| Telugu (te) FLEURS WER | 103.0 (baseline) | 100.1 (−2.8%) |
| Hindi (hi) FLEURS WER | 43.0 (baseline) | 46.3 |
| Tamil (ta) FLEURS WER | 68.2 (baseline) | 70.1 |
| CPU deployment | heavy | ONNX INT8, no GPU needed |
WER = word error rate (lower is better). FLEURS test set, beam=1, punctuation-normalized scoring.
📊 Benchmarks (FLEURS, beam=1, normalized WER)
| Language | Code | Script | v7 (no augment) | v9 final | Δ vs v7 |
|---|---|---|---|---|---|
| Hindi | hi |
Devanagari | 43.0 | 46.3 | +7.7% |
| Tamil | ta |
Tamil | 68.2 | 70.1 | +2.8% |
| Telugu | te |
Telugu | 103.0 | 100.1 | ✅ −2.8% |
| Bengali | bn |
Bengali | 181.3 | 130.2 | ✅ −28.2% |
| Marathi | mr |
Devanagari | 474.9 | 116.9 | ✅ −75.4% |
🧪 The v9 finding: augment per language, not globally
Training with SpecAugment + speed perturbation on all languages damaged Hindi/Tamil (token-loop degeneration) while massively helping Bengali/Marathi. The v9 recipe augments only bn/mr and trains hi/ta/te clean:
| Language | Augmentation | Result |
|---|---|---|
| Hindi, Tamil, Telugu | none (clean) | avoids global-augment damage; stays near the no-augment baseline |
| Bengali, Marathi | SpecAugment + 0.9×/1.1× speed perturb | large gains on hard languages |
🎯 Decoding: per-language beam widths (measured, full FLEURS test)
Beam-5 + repetition penalty 1.3 helps every language except Telugu, where beam search collapses into repeated-token loops (0/472 perfect samples, 326/472 over 100% WER). The library/CLI defaults encode this (num_beams=None → per-language optimal):
| Language | beam-1 | beam-5 + rep 1.3 | Shipped default |
|---|---|---|---|
| Hindi | 46.3 | 45.0 (−2.8%) | beam-5 |
| Tamil | 70.1 | 68.6 (−2.2%) | beam-5 |
| Telugu | 100.1 | 120.5 (+20.4% ⚠️) | beam-1 |
| Bengali | 130.2 | 126.4 (−2.9%) | beam-5 |
| Marathi | 116.9 | 91.5 (−21.7%) | beam-5 |
📦 Which adapter should I use?
| Language | Adapter file | Backbone | WER |
|---|---|---|---|
Hindi (hi) |
polywhisper_output_hi/adapters_v3/hi_best_clean.pt |
openai/whisper-small |
46.3 |
Tamil (ta) |
polywhisper_output_ta/adapters_v3/ta_best_clean.pt |
openai/whisper-small |
70.1 |
Telugu (te) |
polywhisper_output_gpu0/adapters_v3/te_best_prod.pt |
openai/whisper-small |
100.1 |
Bengali (bn) |
polywhisper_output_gpu0/adapters_v3/bn_best_prod.pt |
openai/whisper-small |
130.2 |
Marathi (mr) |
polywhisper_output_gpu1/adapters_v3/mr_best_prod.pt |
openai/whisper-small |
116.9 |
All adapters are rank-16 LoRA (decoder + encoder attention), ~14MB each. Backbone weights are not included — they load from openai/whisper-small at runtime. The _prod suffix is the v9 production-run tag, not an augmentation marker: Telugu was trained clean in the selective v9 recipe.
🚀 Quickstart
pip install -e .
# Hindi speech to text
polywhisper transcribe audio.wav --lang hi

# Tamil with JSON output
polywhisper transcribe audio.wav --lang ta --format json

# Auto-detect language, SRT subtitles
polywhisper transcribe audio.wav --format srt > subs.srt

# Batch a folder
polywhisper batch ./audio_folder/ --lang bn --output results.json
from polywhisper import transcribe

result = transcribe("audio.wav", lang="mr")
print(result.text)
print(result.segments)  # timestamped segments
🖥️ CPU-only inference (ONNX Runtime)
Export INT8-quantized ONNX graphs (no PyTorch, no GPU needed at inference):
polywhisper export --lang hi --variant prod --int8
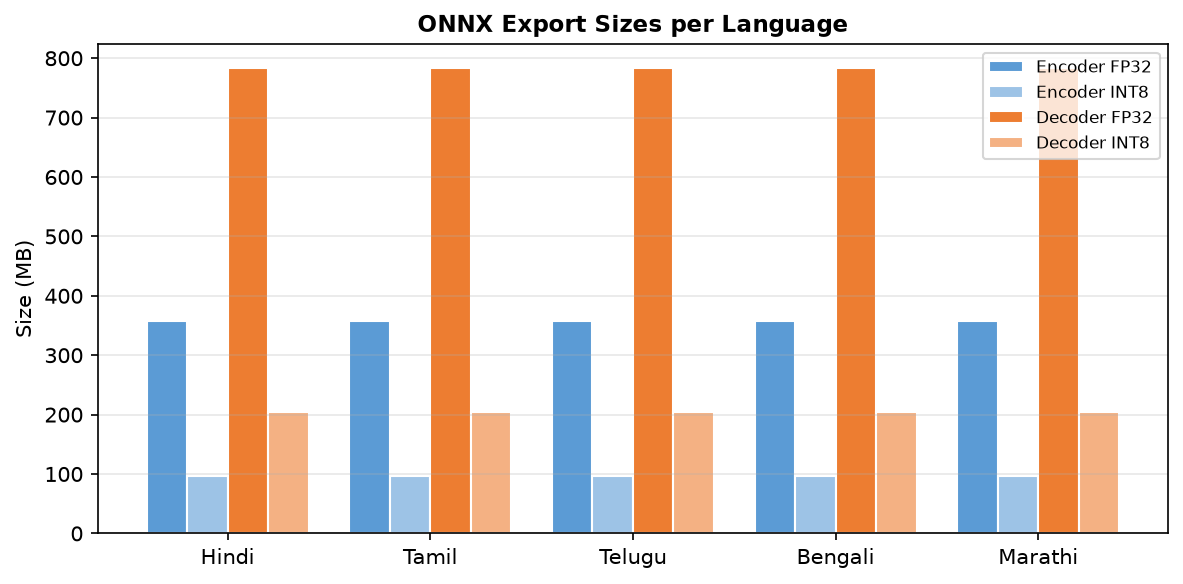
Pre-exported v9 graphs live under export/onnx/ on the Hub — per language, fp32 + INT8:
| Lang | Encoder (fp32 / INT8) | Decoder (fp32 / INT8) |
|---|---|---|
| hi | 358MB / 97MB | 784MB / 204MB |
| ta | 358MB / 97MB | 784MB / 204MB |
| te | 358MB / 97MB | 784MB / 204MB |
| bn | 358MB / 97MB | 784MB / 204MB |
| mr | 358MB / 97MB | 784MB / 204MB |
Files are named {lang}_{lang}_best_prod_{encoder,decoder}{,_int8}.onnx. INT8 is ~4× smaller.
Verification: fp32 ONNX vs PyTorch max diff < 1e-3 on all five languages (encoder + decoder). End-to-end greedy spot-checks (FLEURS audio, beam=1):
| Lang | torch WER | ONNX INT8 WER |
|---|---|---|
| hi (10 samples) | 43.4% | 48.3% |
| ta (5 samples) | 100.0% | 100.0% |
| te (5 samples) | 100.0% | 101.6% |
| bn (5 samples) | 104.9% | 118.7% |
| mr (5 samples) | 82.9% | 89.4% |
Spot-checks are tiny (5–10 utterances) so single-sentence flips move the numbers; fp32 ONNX is at parity with torch. INT8 trades a few points for 4× smaller files.
🏋️ Training recipe (reproducible)
- Data: IndicVoices-ST (~19–20k clips/language) · Eval: FLEURS
- Backbone:
openai/whisper-small, frozen · Adapters: LoRA rank-16, encoder + decoder attention - Schedule: 3–5 epochs/language, batch 4, AdamW, cosine LR (peak 1e-4), 2× NVIDIA T4
- Augmentation (v9): SpecAugment + speed perturb for
bn/mronly;hi/ta/teclean - Selection: WER-gated checkpoints (
*_best_*.pt) on FLEURS dev slices - Code:
train_v3.py· orchestratorkaggle_train_resumable.py· scoringnormalize_ortho.py
❓ FAQ
What is PolyWhisper? PolyWhisper is an open-source Indic ASR toolkit: one frozen Whisper-Small backbone plus five small per-language LoRA adapters covering Hindi, Tamil, Telugu, Bengali, and Marathi.
How is it different from fine-tuning Whisper?
Full fine-tuning rewrites 244M–1.5B weights per language. PolyWhisper freezes the backbone and trains ~3.5M LoRA parameters per language (14MB), so five languages ship for the storage cost of a rounding error.
Which languages are usable? All five ship working adapters. Hindi (46.3 WER) and Tamil (70.1) are strongest; Telugu, Bengali, and Marathi remain high-WER research adapters, useful for assistive/search/subtitle-draft workflows rather than verbatim transcription.
Can I run it on CPU? Yes — export to ONNX INT8 and run with ONNX Runtime, no GPU required.
Can I run it on a Mac?
Yes — PyTorch MPS is supported (Device: mps), plus CPU via ONNX.
What data was it trained/evaluated on? Trained on IndicVoices-ST conversational speech, evaluated on FLEURS read speech with punctuation-normalized, script-aware scoring.
⚠️ Limitations
- Absolute WER on Telugu/Bengali/Marathi is still high — usable for assistive/search/subtitle-draft workflows, not verbatim legal/medical transcription.
- Evaluated on read speech (FLEURS); spontaneous conversational accuracy will differ.
- Beam=1 numbers in the benchmark table above (paper parity); shipped defaults use beam-5 + repetition penalty 1.3 except Telugu (beam-1), see decoding table.
📄 License & citation
MIT. Whisper weights © OpenAI. Training data: IndicVoices-ST (CC-BY) · Eval: FLEURS (CC-BY).
@misc{polywhisper2026,
  title  = {PolyWhisper: Efficient Multilingual Indic ASR via Frozen Backbone and Per-Language LoRA Adapters},
  author = {Kishore, Gautam},
  year   = {2026},
  publisher = {HuggingFace},
  url    = {https://huggingface.co/eulogik/polywhisper}
}
🔗 Links
- 🌍 Eulogik: eulogik.com
- 🤗 Model: huggingface.co/eulogik/polywhisper
- 💻 Code: github.com/eulogik/PolyWhisper
- 🗣️ Train data: ai4bharat/indicvoices-st
- 🧪 Eval data: google/fleurs